Jev Harness for Claude Code and Codex: Route, Permit and Verify
How to design a coding-agent runtime that chooses context, models and tools per turn, gates risky actions, records receipts and measures real accepted-task cost.
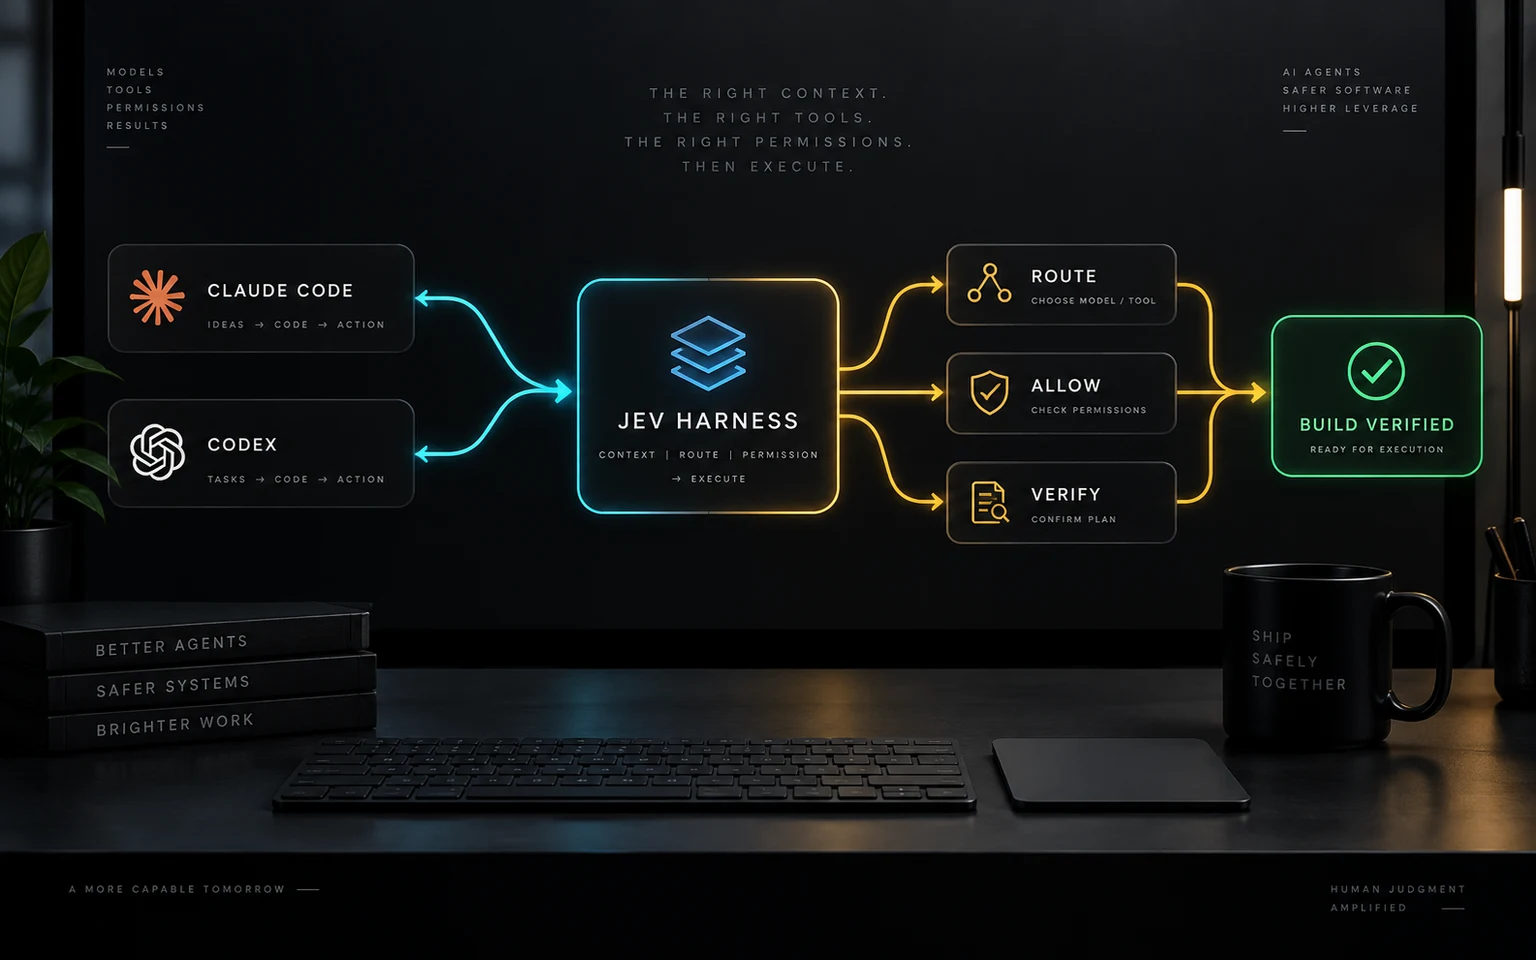
Jev Harness blueprint for coding agents
Watch the original post and video on X
An agent harness is the runtime around a model that decides what context a turn sees, which model or tool handles it, and whether an action may run. A Jev-style harness adds narrow, structured decisions while host code retains policy and execution. Claude Code and Codex users can apply the pattern with conditional instructions, tool allowlists, approval gates and evaluations, but the social 200× faster and 400× cheaper claims require testing on real tasks.
- The LLM proposes, a decision layer reviews narrow questions, and host code authorizes execution
- Reduce context and schemas only when capability is preserved
- Keep routing, permission and verification separate
- A receipt is evidence—not execution authority
- Roll out through baseline, shadow mode and limited low-risk tasks
The harness is the system around the model
A coding agent includes a context builder, tool catalog, permission policy, executor, sandbox, memory and evaluation—not only an LLM. The harness decides what the agent sees, what it can do and where it stops.
Jev is proposed as a decision layer for bounded choices such as route, tool, risk or success, while the host remains responsible for policy and execution.
Separate four decisions
- Context: which files, instructions and history are necessary
- Route: which model, skill, sub-agent or tool fits the task
- Permission: allow, ask or deny under current scope
- Verification: whether typecheck, tests, security and acceptance criteria pass
Apply the pattern without building a new platform
These controls provide value even before a team integrates a Jev API.
- Use AGENTS.md as the source of truth
- Load directory-specific instructions conditionally
- Allowlist tools and request approval for network, secrets, deploys or deletion
- Require a plan or patch before execution
- Run builds and tests, then read back the result
- Record task, context version, tool, diff, tests and reviewer as a receipt
Read the 200× and 400× claims correctly
The source social post summarizes the blueprint as 200× faster and 400× cheaper. The available implementation notes do not establish that as a universal end-to-end coding-agent benchmark.
Real cost includes context rebuilds, caching, routing overhead, tool calls, retries, tests and human review. A cheaper routed model can cost more if it must re-read context or repair work repeatedly.
Baseline, shadow, then limit risk
- Record tokens, latency, tool use, pass rate and human time
- Let routing recommendations run in shadow mode
- Check whether reduced context or tools lowers completion
- Enable only low-risk tasks with caps and manual fallback
- Expand after regression tests and receipt review pass
Build agents that ship verifiable work
Our Claude Code + Cowork workshop covers project instructions, skills, connectors, GitHub, deployment and scheduled workflows with approval. Participants can start with internal or Google Workspace automation before building a web app.
Explore the Claude Code + Cowork workshopFrequently asked questions
What is a Jev harness?
It is a pattern for adding structured routing and review decisions to an agent runtime while host code retains policy and execution.
Will it make Claude Code or Codex 200× faster?
That is not established for every end-to-end workflow. Benchmark it against your real tasks, baseline and acceptance criteria.
Does a receipt authorize execution?
No. It supports audit and replay; the host still enforces authorization, sandboxing and permissions.
Can I start without Jev?
Yes. Begin with conditional context, tool allowlists, approvals, build/test verification and logs, then test a decision model against the baseline.
Sources
- [1] Jev Harness blueprint social summary — darkzodchi on X · accessed 2026-09-28
- [2] Jev Harness repository and implementation boundaries — TypeSafeAI community repository · accessed 2026-09-28